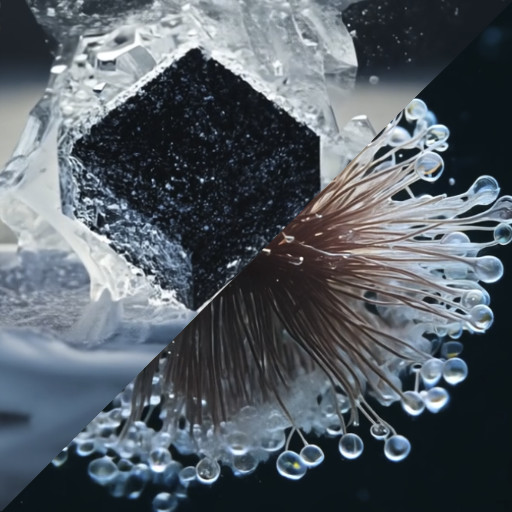
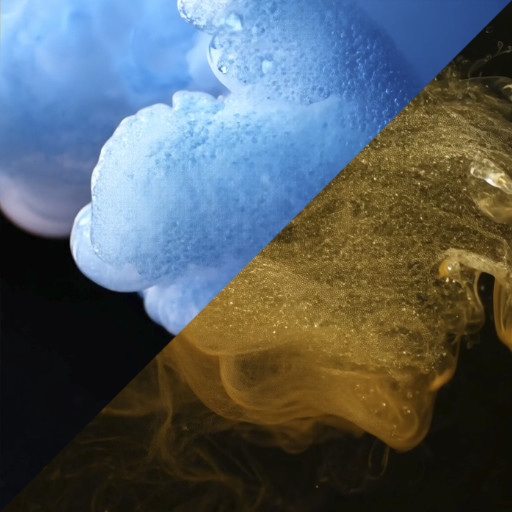
In July 2024, RunwayML released a new model named Gen-3 Alpha. Out of curiosity, I wanted to know how far these Text-to-Image commercial diffusion models have reached especially for generating videos which are hard, expensive to shoot or candidates of VFX. The first systematic test I did was about fluid sim stuffs with a focus of physical state changes. The result was quite stunning but also a bit scary because all these 10-second videos were generated ‘under a few minutes’.
Through repeated trial-and-errors, one would learn a set of keywords that work best for the desired visuals; then it took some good patience to carefully select (lucky draws actually) random seeds that would work well in the targeted visual context, i.e. the latent space. The very last example (down to the bottom) was the one that steered me to another test which was about organic looking stuffs.