Diffusion models available today often present themselves as powerful and generic image or video generator that they produce content based on user text prompts. This impression was simply a direct result of the design choices of these models. Driven by a goal of understanding better how diffusion model works, I trained a diffusion model from scratch myself for an image subject that I truly enjoy to photograph or sometimes to simulate using physically based methods. Summer cumulus clouds is what I love the most to photograph.
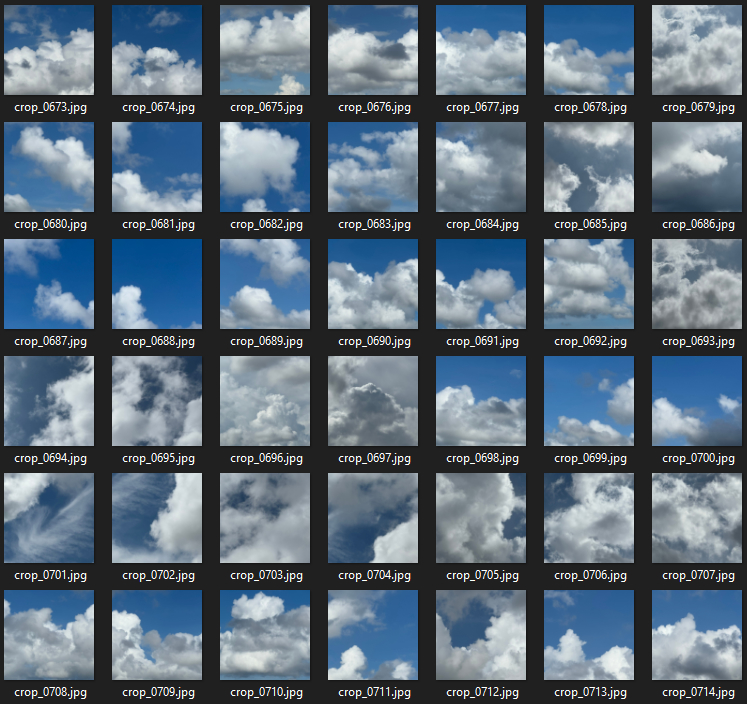
Most images were shot during the 2025 Summer in Hong Kong, using the telephoto lens of an iPhone 15 Pro (it shoots like a 70mm lens I guess). The main article I follow was a SIGGRAPH 2023 paper titled ” Iterative 𝛼-(de)Blending: a Minimalist Deterministic Diffusion Model” by Heitz, Belcour and Chambon, and they even prepared a very good explainer.
At the beginning, I followed their sample code but I quickly realized that they simply relied on the Diffusion UNet from the HuggingFace library and this was not what I expected because I wanted to understand how various comopments in the models contribute to the end result with experiments. At the end, I coded the model from scratch using PyTorch layers. To be honest, to put together a model in PyTorch is a fairly straight forward task especially when we compare to any rendering research effort. This from-scratch exercise allowed me to learn and catch up many latest development in machine learning since I completed my last ResNet based denoiser project (my Ph.D. Thesis)
The final model architecture I chose is minimalistic, it is basically a 6-layer denoising UNet (on both downsample and upsample direction) using group normalization and the required time-embedding. Absolutely no attention layer is used. A model size of 22MB is good enough to learn the statistics very well and I even managed to push for a very small one of size 9.5MB.
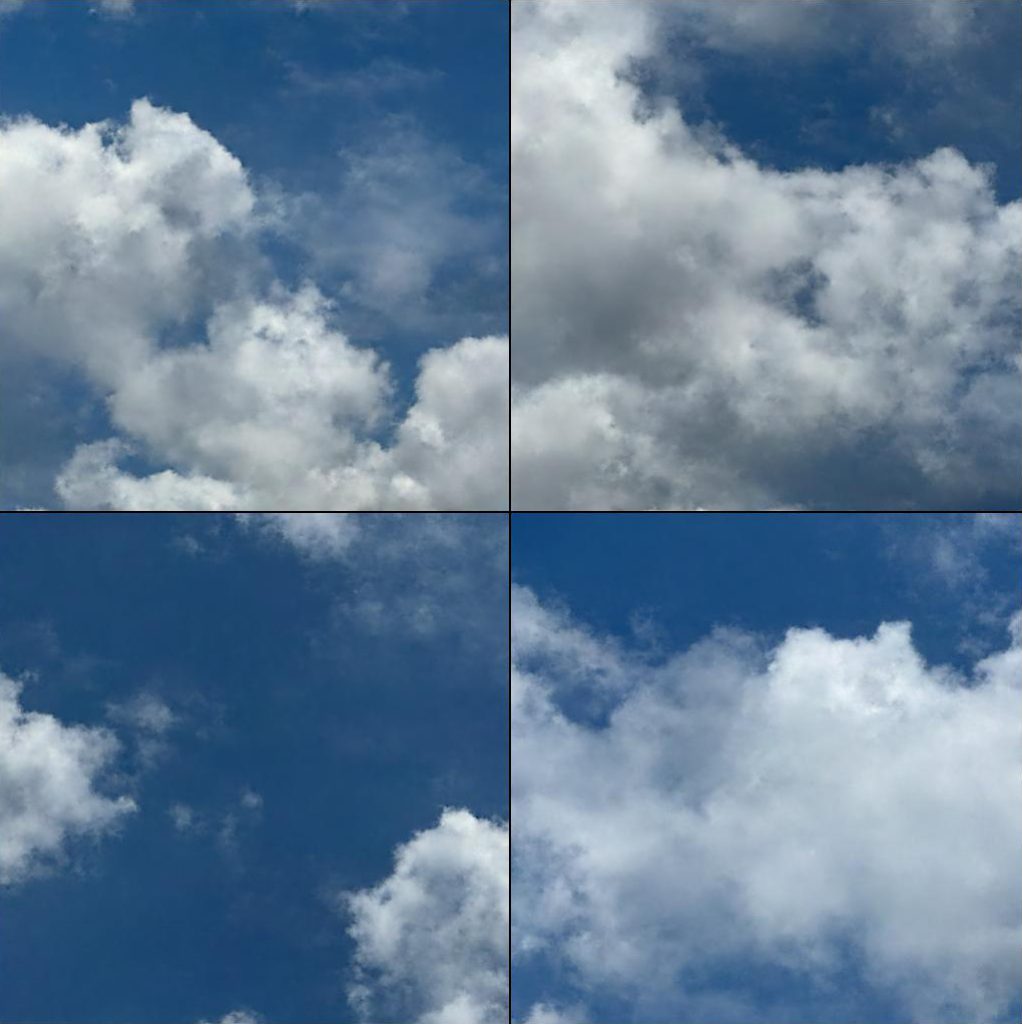
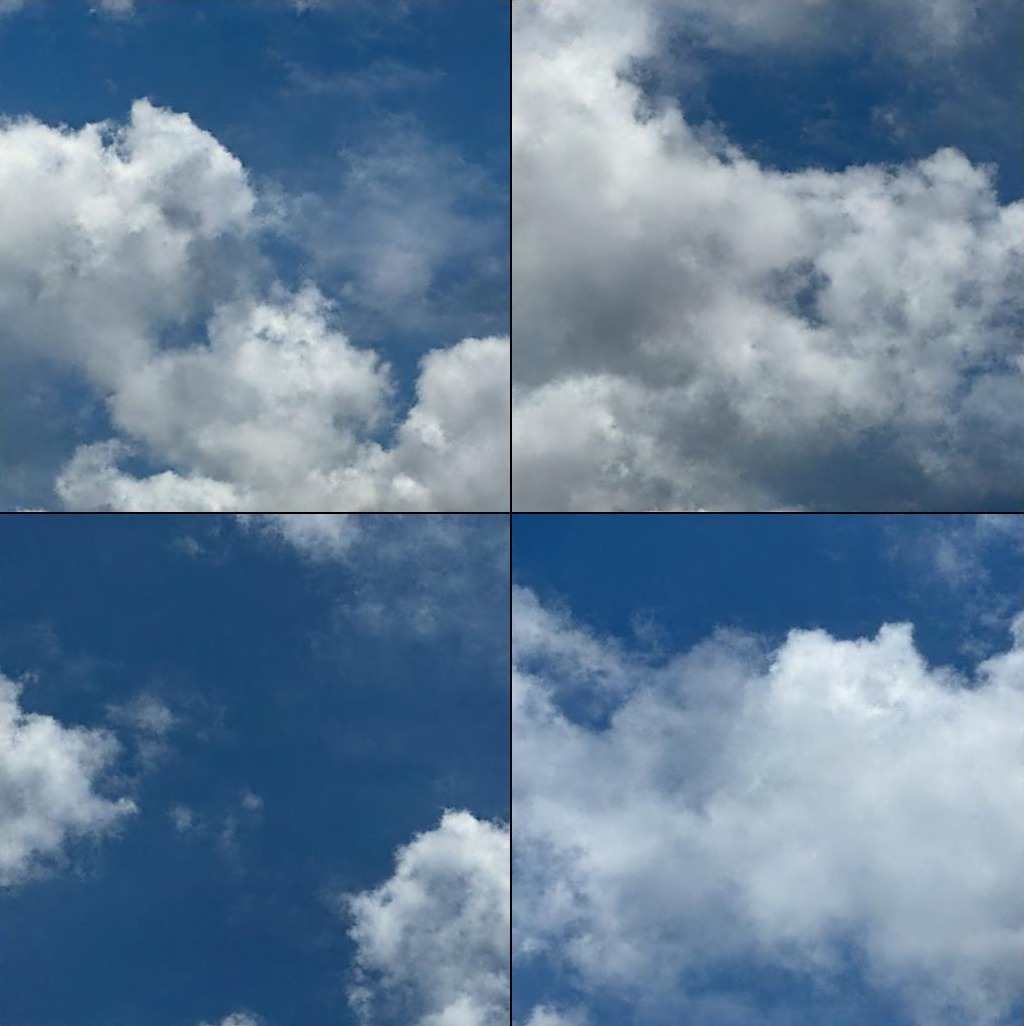
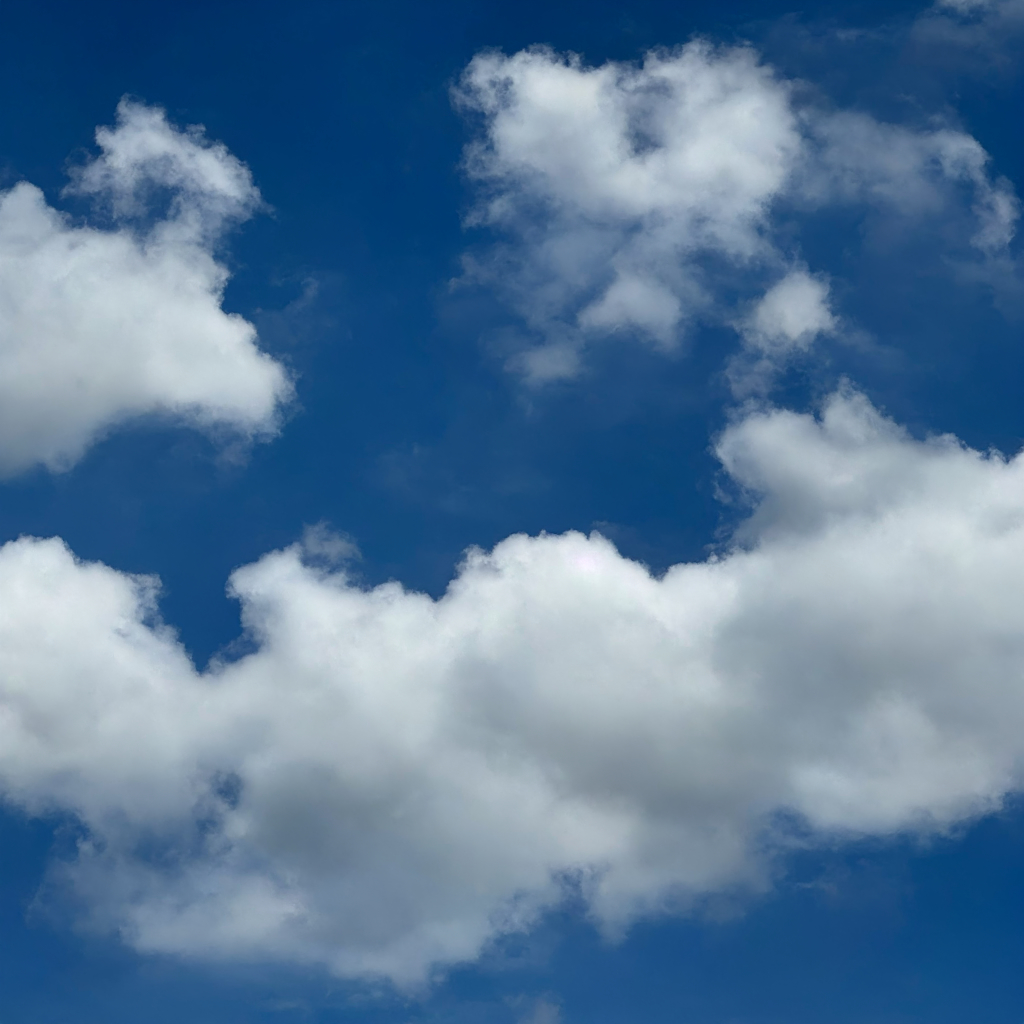
The images above are generated from a model with the filter configuration (# of filters in each denoising layer) of {32, 64, 96, 128, 160, 192}, 32 for group normalization and time-embedding dimension of 512. Since a simple pixel-space diffusion model functions like a filter, so it’s possible to feed image of arbitrary size into the denoiser, and the image below is from an input of 1024 x 1024 noisy image.
At the moment, many improved diffusion approaches are already available, e.g. flow matching or mean flow for one-step denoising etc. I am planning to extend the experiment for conditional generation.